
Enterprise infrastructure / server clusters
Server clusters
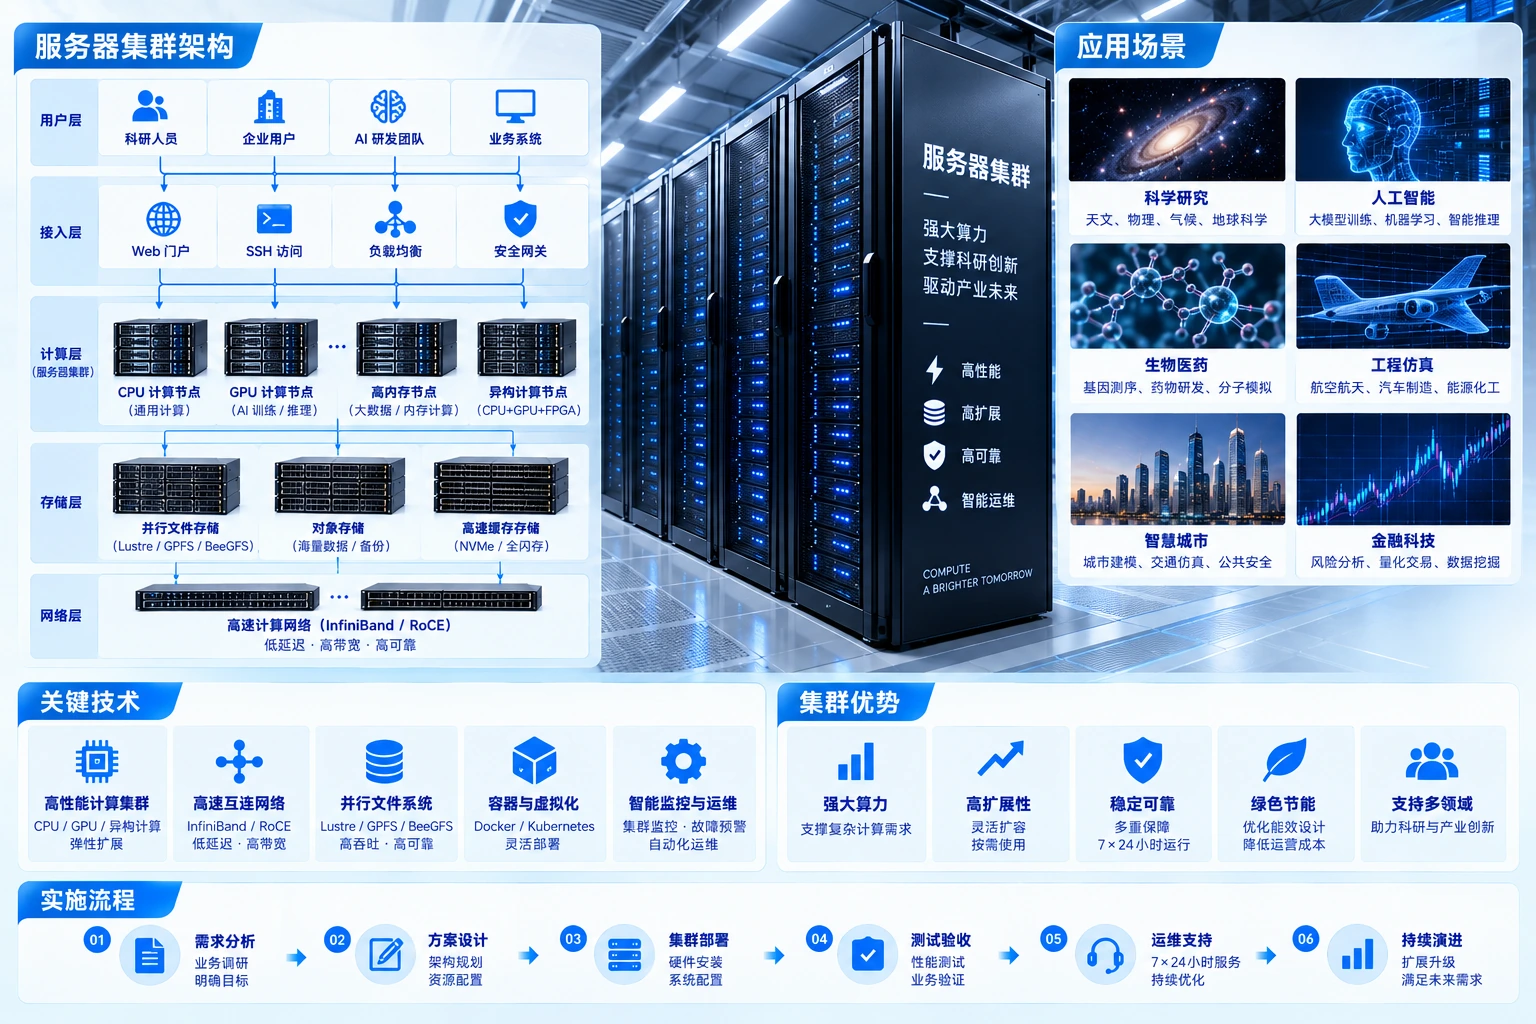
Yuqi Intelligent provides workload assessment, node selection and supply, cluster deployment, pilot testing and delivery support so multi-node business or compute tasks have a workable hosting relationship.
Separate business continuity from parallel tasks before deciding on nodes, data and validation relationships.
01 / direction
High-availability hosting or parallel-compute coordination
High-availability hosting focuses on applications, data consistency and failover; parallel computing focuses on program parallelism, task scheduling and data access. Selection should follow the actual way of working.
- Compute node 01
- Compute node 02
- Compute node 03
02 / service scope
From current environment to pilot handover
The actual scope follows site conditions, business windows and the acceptance goals confirmed by both parties.
Current-state and workload assessment
Review business dependencies, task types, capacity, performance and the current environment to define the high-availability or parallel-compute boundary.
Node selection, quotation and supply
Define node configurations, quotations and delivery lists around compute, memory, local disks, NICs and expansion requirements.
Interconnect and storage planning
Plan node interconnects, shared storage or data-access relationships, and check network, rack, power and port conditions.
HA platform or scheduler deployment
Deploy an HA platform for the actual workload, or configure job queues, scheduling and compute-node coordination.
Switching, job pilot and testing
Validate failover, job submission, node coordination and data access in the agreed window, recording actual results.
Monitoring, documentation and handover
Deliver configuration records, operating boundaries, monitoring recommendations, pilot results and expansion references.
Client delivery
Configuration, validation and operating basis
If you also need to check servers and storage hosting,SAN and storage virtualization boundary or high-performance computing HPC resource relationships, we record nodes, interconnects, data access and operating ownership together.
- Node, network and storage configuration list
- Platform topology and key operating parameters
- Pilot, switch or job-validation records
- Monitoring, alerts and daily operations guidance
- Operations documentation and expansion recommendations
Frequently asked questions
Confirm the workload before the architecture
What is the difference between high availability and parallel computing?
High availability addresses business continuity, failover and data consistency. Parallel computing coordinates parallelizable tasks across a scheduler and multiple compute nodes. They may share infrastructure, but one cannot substitute for the other by name alone.
Can older servers still be used?
Check processor generation, memory, NICs, disk health, warranty, power and compatibility first. Suitable older nodes may serve testing, supporting or tiered roles; unsuitable ones are marked clearly in the solution.
What is validated before go-live?
Within the actual scope, validate node reachability, interconnects, data access, scheduling or switch procedures, representative jobs and monitoring alerts. The production window and acceptance conditions are confirmed before implementation.